Shipped to frontier AI labs
We have shipped training and evaluation environments to frontier AI labs, built on real business logic and verified task by task. That same technology now helps power the models behind our newer products, including Manifest. It runs on two surfaces: the Platform, where tasks are authored, evaluated, and quality-checked, and Build, a no-code way to compose environments from blocks.
Platform
The evaluation pipeline behind Transpira's agents: where we author benchmark tasks, run them against frontier models, and validate every trace before a capability is trusted with real operational work.
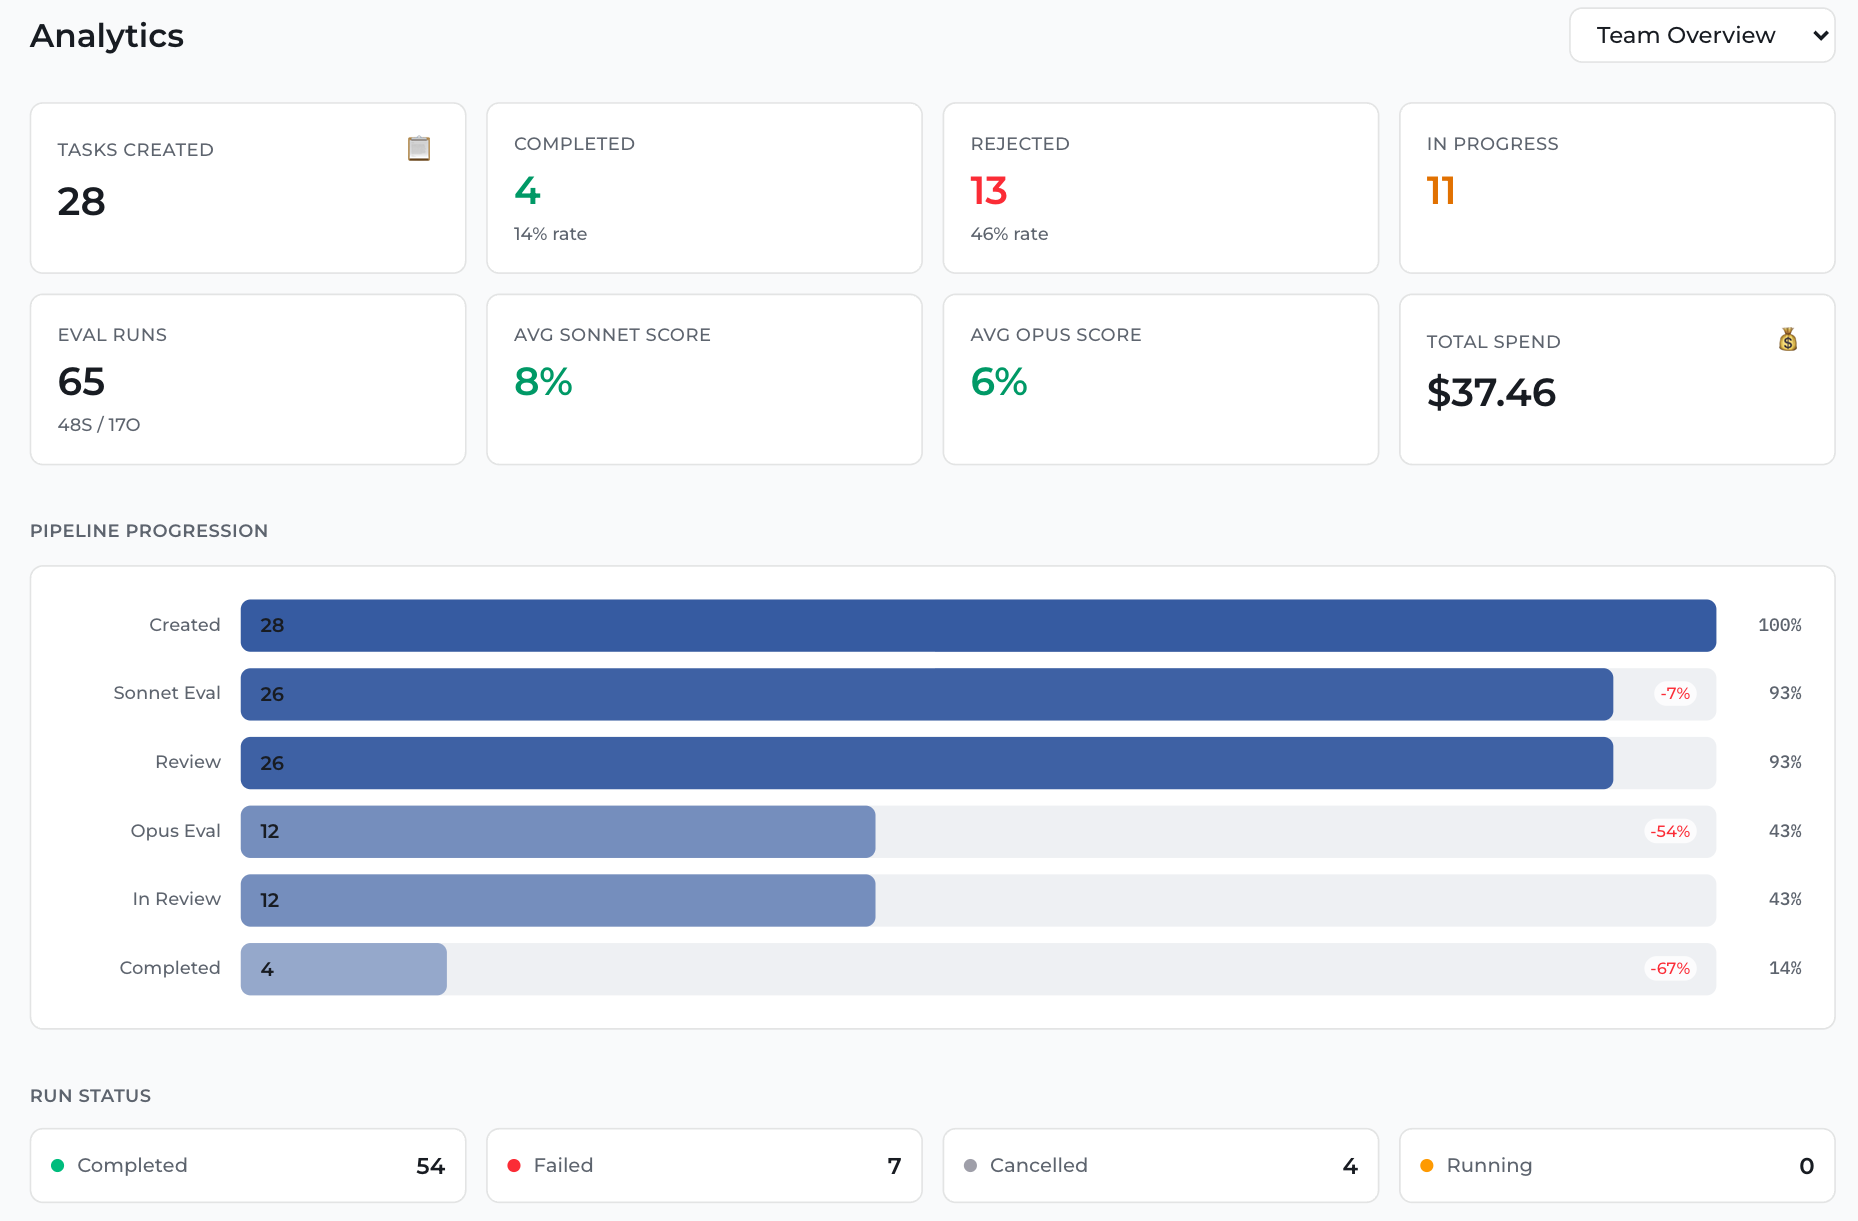
Track every task from draft to done.
Watch work move through the pipeline with per-model scores, run status, and spend in one view.
Build
Where Transpira's agents train: composing reinforcement-learning environments from blocks described in plain language, then building, running, and testing them against operational scenarios.
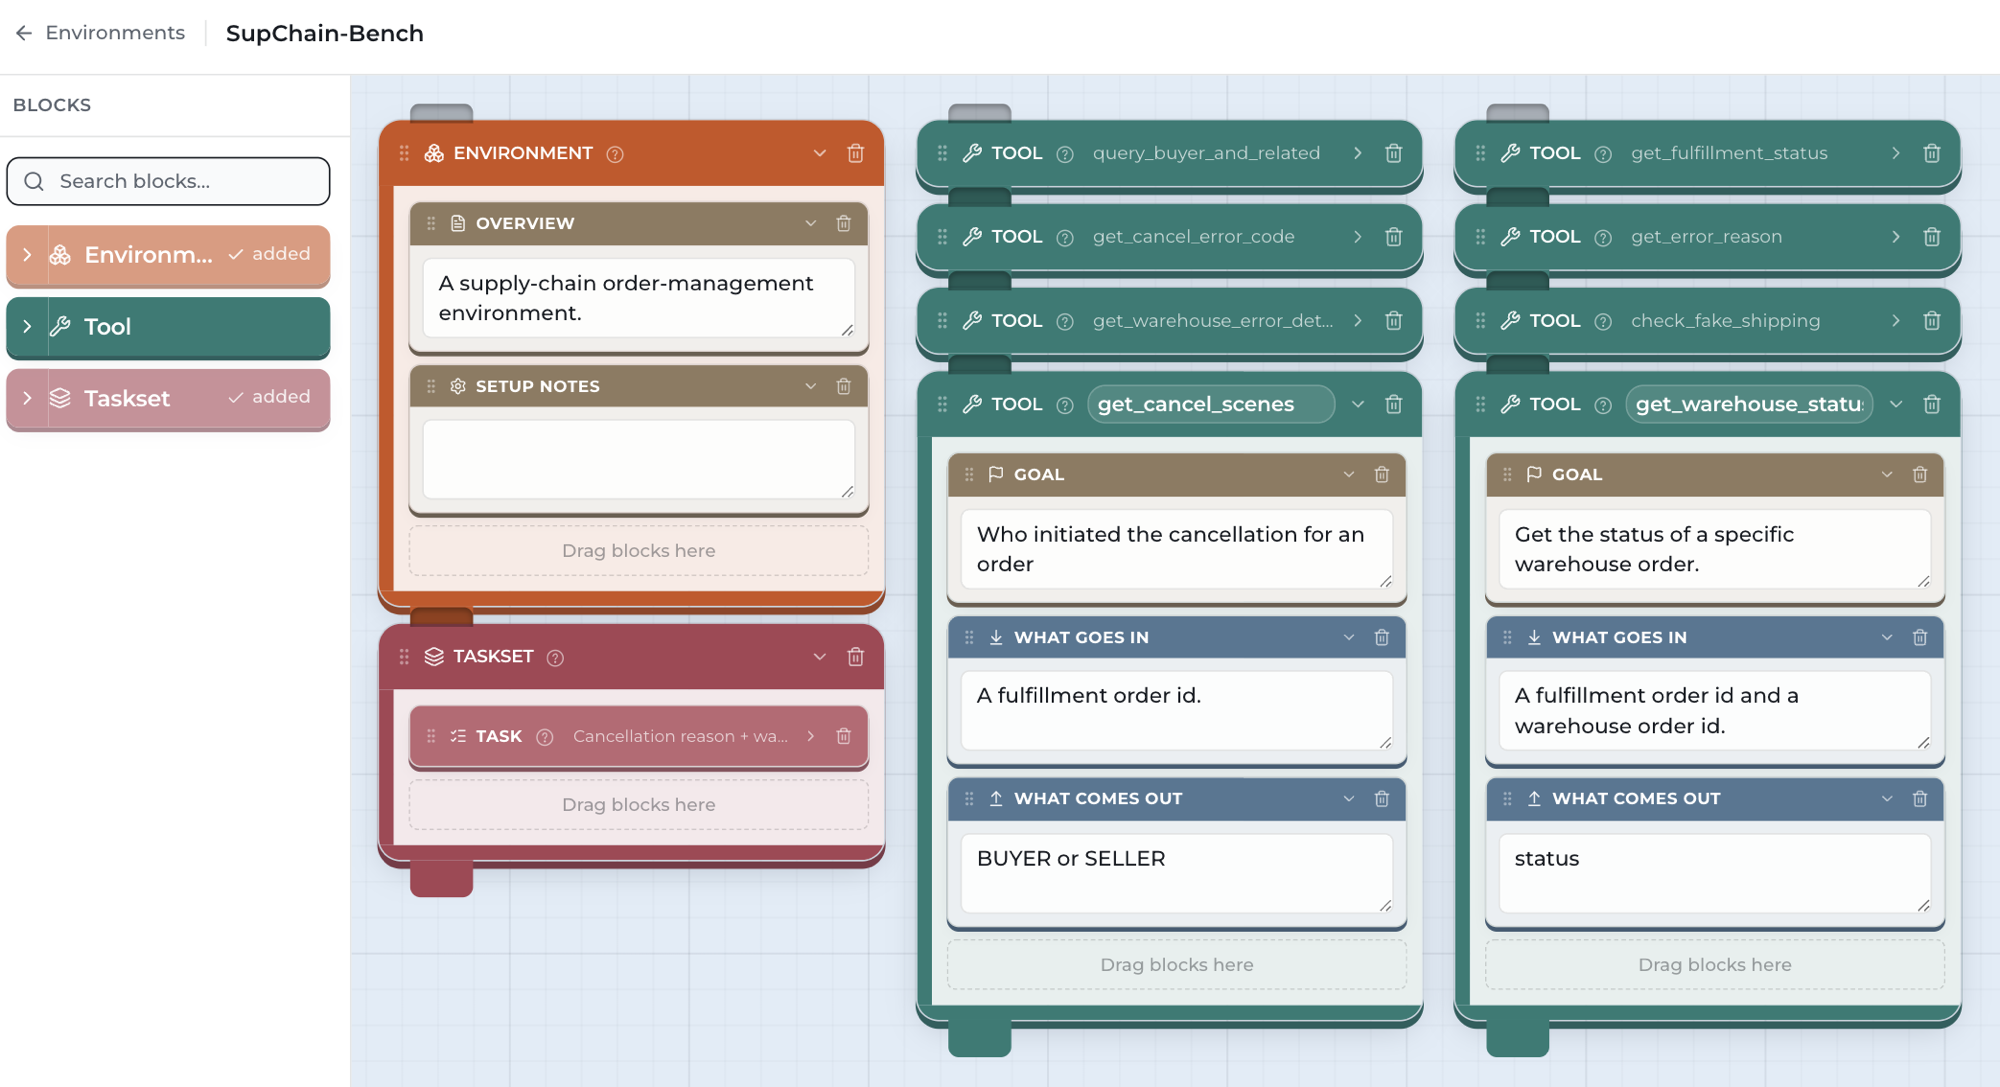
Compose an environment from blocks.
Lay out an environment as a chain of blocks described in plain language and wired to the next. No code required.
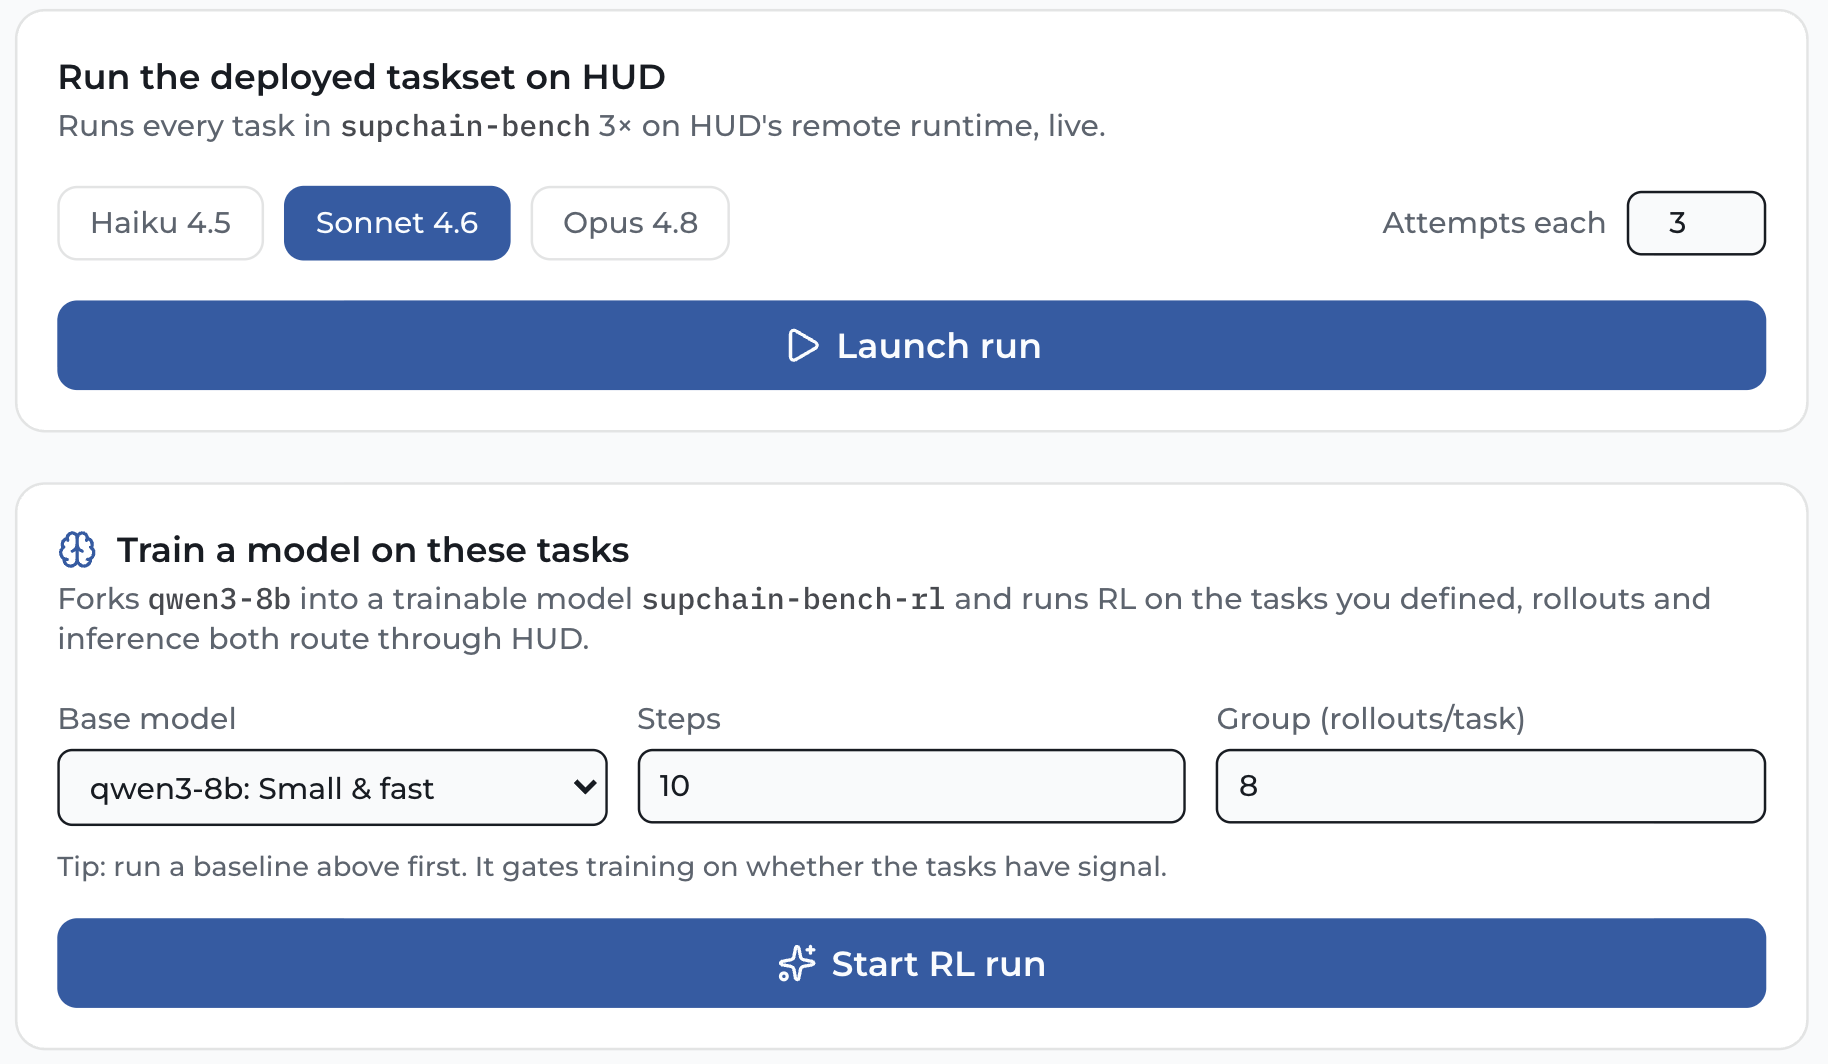
Run, test, and tune in place.
Send an agent through the environment you composed and watch it resolve, retry, and recover live. Then adjust the reward and run it again.